The alert arrives before the engineer does
Multi-source ingestion, alert correlation and noise reduction, tiered on-call and automatic ticket dispatch — turning operations from firefighting into fire prevention.
Operations is often the under-estimated part of a project: the lack of effective monitoring and management only becomes obvious after go-live. Our Unified O&M Monitoring service ingests network devices, servers, storage, databases and business-critical applications through SNMP, Syslog, agents and APIs; applies custom alert rules and notification policies; and supports root-cause analysis and automated response. A CMDB acts as the single source of truth for all operational data, keeping asset records, configuration changes and dependencies accurate.
Multi-source ingestion and unified monitoring
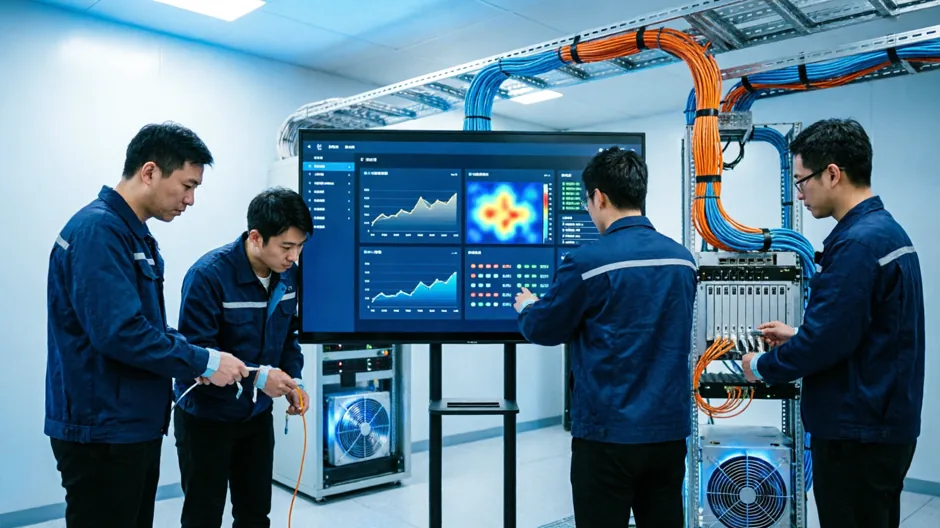
Full-chain monitoring covers network devices (switches, routers, firewalls, wireless controllers), servers (physical, virtual, container), storage, databases and business-critical applications.
SNMP, Syslog, agents and APIs feed one monitoring platform, so you stop running several tools that do not talk to each other.
- Full-chain network and server monitoring
- SNMP / Syslog / Agent / API ingestion
- Storage, database and application monitoring
- Unified monitoring platform and views
- Business availability monitoring (APM)
Alert correlation and noise reduction
More alerts is not better. Correlation and suppression rules collapse a flood of raw alerts into a small set of actionable events, so an alert storm never buries the real problem.
Thresholds and notification policies are fully customisable, and automated response scripts can be attached.
- Alert correlation and suppression
- Dynamic threshold and baseline adjustment
- Root-cause analysis assistance
- Automated response script triggers
- WeCom / SMS / email notification
Tiered on-call and ticket dispatch
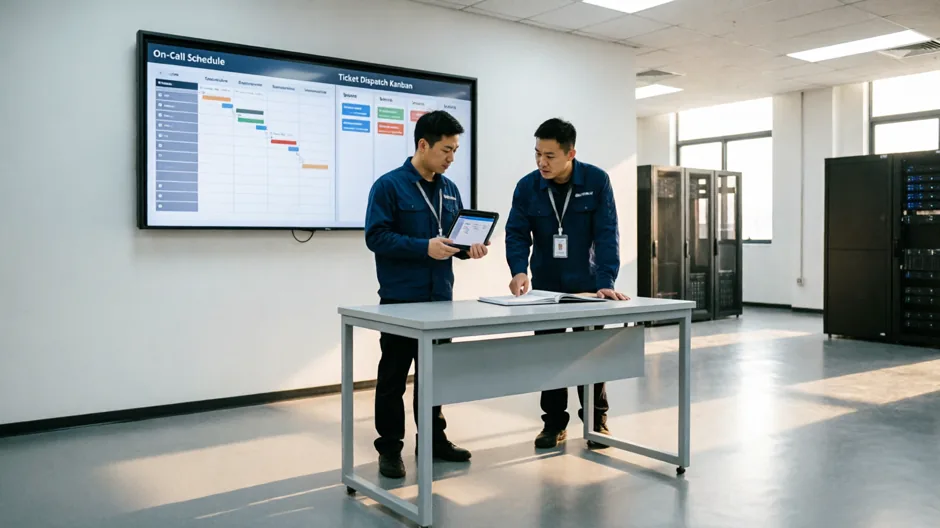
Alert severity maps to an on-call tier; tickets are dispatched automatically to a named owner and escalate on timeout, with the whole handling trail recorded.
From detection to response to closure, operations becomes a measurable process.
- Tiered on-call and shift management
- Automatic dispatch and timeout escalation
- Traceable handling history
- Ticket closure and follow-up
- Emergency response plan integration
CMDB and SLA reporting
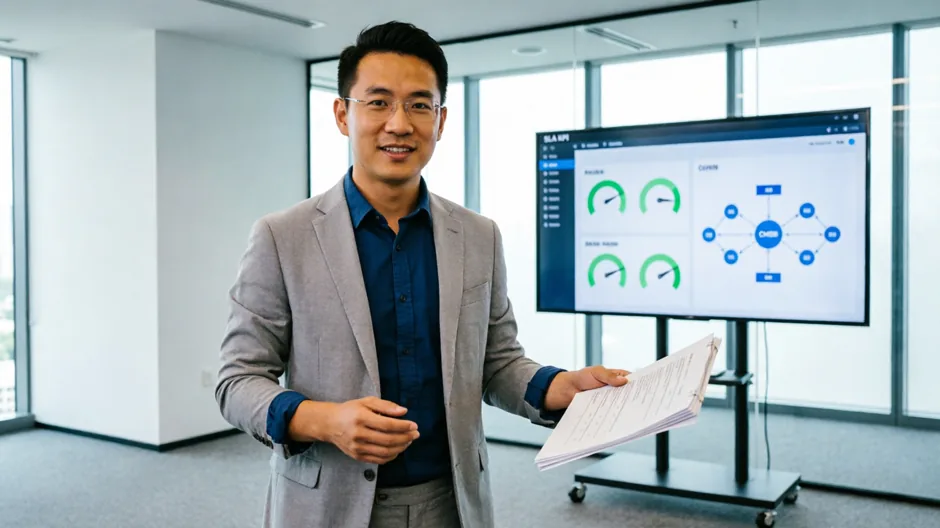
The CMDB is the single source of truth for operational data, with a unified configuration model spanning hardware assets, software licences, network topology and application dependencies.
Key metrics are visualised — MTTR, MTBF, utilisation trends and SLA attainment — so the value of operations is visible.
- CMDB configuration management build-out
- Configuration change and approval workflow
- MTTR / MTBF and availability reporting
- SLA visualisation and attainment analysis
- Capacity trends and optimisation recommendations
Computer System Validation (CSV)
An auditable validation evidence chain delivered on the GAMP 5 V-model.
View details →
Data Center Migration
A six-step migration process where every step can be rolled back.
View details →
Digital Desktop (VDI)
Pooled and dedicated desktops, with data that never leaves the data center.
View details →
Network & Security Services
Enterprise networks, industrial networks, SD-WAN and full-stack security.
View details →
IT Architecture Consulting & Planning
Current-state assessment, evolution roadmap and investment prioritisation.
View details →Need expert service support?
Tell us how your systems look today and we will give you a route that actually works.
Book a free consultation